


Semantic model duplication is the reason two Power BI reports in the same company can show two different numbers for “revenue,” “active customers” or “on-time delivery,” and both can be technically correct. Someone copied a model, tweaked a measure, published it to a different workspace, and a few months later nobody remembers which version the board should trust. The dashboards look identical. The numbers don’t match.
Thank you for reading this post, don't forget to subscribe!This guide explains how semantic model duplication happens, why it’s so hard to spot, and the practical steps you can take to bring your reports back to one version of the truth. If you’d like hands-on skills in this area, we’ve linked to Power BI courses in Australia near the end.
What Is Semantic Model Duplication in Power BI?
A Power BI semantic model (previously called a dataset) holds your tables, relationships and measures. Reports sit on top of it. Semantic model duplication happens when several near-identical models exist for the same business subject, each with its own copy of the data logic and its own versions of the calculations.
Microsoft’s Power BI documentation on Microsoft Learn explains how semantic models are meant to be shared and reused across many reports. The problem is that it’s easy to build a new model and hard to find an existing one, so people quietly start again.
If you’ve read our post on Power BI measure sprawl, think of that as the symptom and semantic model duplication as one of the deeper causes.
How Semantic Model Duplication Happens
Someone “just needs a quick report”
A manager wants a slightly different view. The fastest route is to download the PBIX file, change a few things and publish it as a new report with its own embedded model. It takes an hour. Six months later there are forty of them.
Report authors can’t find the trusted model
If there’s no endorsement, no naming convention and no catalogue, a new analyst has no way to know that a certified model already exists. Building their own feels responsible.
Teams work in separate workspaces
Finance, sales and operations each build in their own space. Each team’s model is reasonable on its own. Together they’re three versions of “customer.”
Measures get written in the report, not the model
When a report is connected to a shared model, authors can still add report-level measures. It’s a handy feature, but it means the same KPI can be redefined in dozens of places without touching the central model.
Nobody owns the model
With no accountable owner, there’s no one to say no to a duplicate or to retire an old one. This ties directly to dashboard ownership and the KPI ownership gap.
A Semantic Model Duplication Example: Three Reports, Three Revenues
Imagine three reports, each with its own copy of the sales model. The definition of revenue looks innocent in all three:
Revenue (Sales report) = SUM ( Sales[Amount] )
Revenue (Finance report) = SUMX ( Sales, Sales[Qty] * Sales[UnitPrice] )
Revenue (Ops report) = CALCULATE ( SUM ( Sales[Amount] ), Sales[Status] <> “Cancelled” )
The first includes everything. The second recalculates from quantity and price, ignoring discounts. The third removes cancelled orders. All three are called “Revenue,” all three are defensible, and no two will ever match. This is exactly the KPI definition gap in action, multiplied by the number of copies of the model.
The Cost of Semantic Model Duplication
- Conflicting numbers. Meetings turn into arguments about whose report is right.
- Eroded trust. Once leaders see two figures for the same thing, they start to doubt all of them. Our article on confidence in data explores why that matters so much.
- Wasted effort. Every fix has to be repeated in every copy, and some copies get missed.
- Slower refreshes and higher capacity use. Multiple models importing the same data repeat work for no reason.
- Security gaps. Row-level security set up in one model may be missing in its copy.
- Unused dashboards. People abandon reports they can’t trust, which feeds the problem described in our post on dashboard adoption.
How to Fix Semantic Model Duplication: 7 Practical Steps

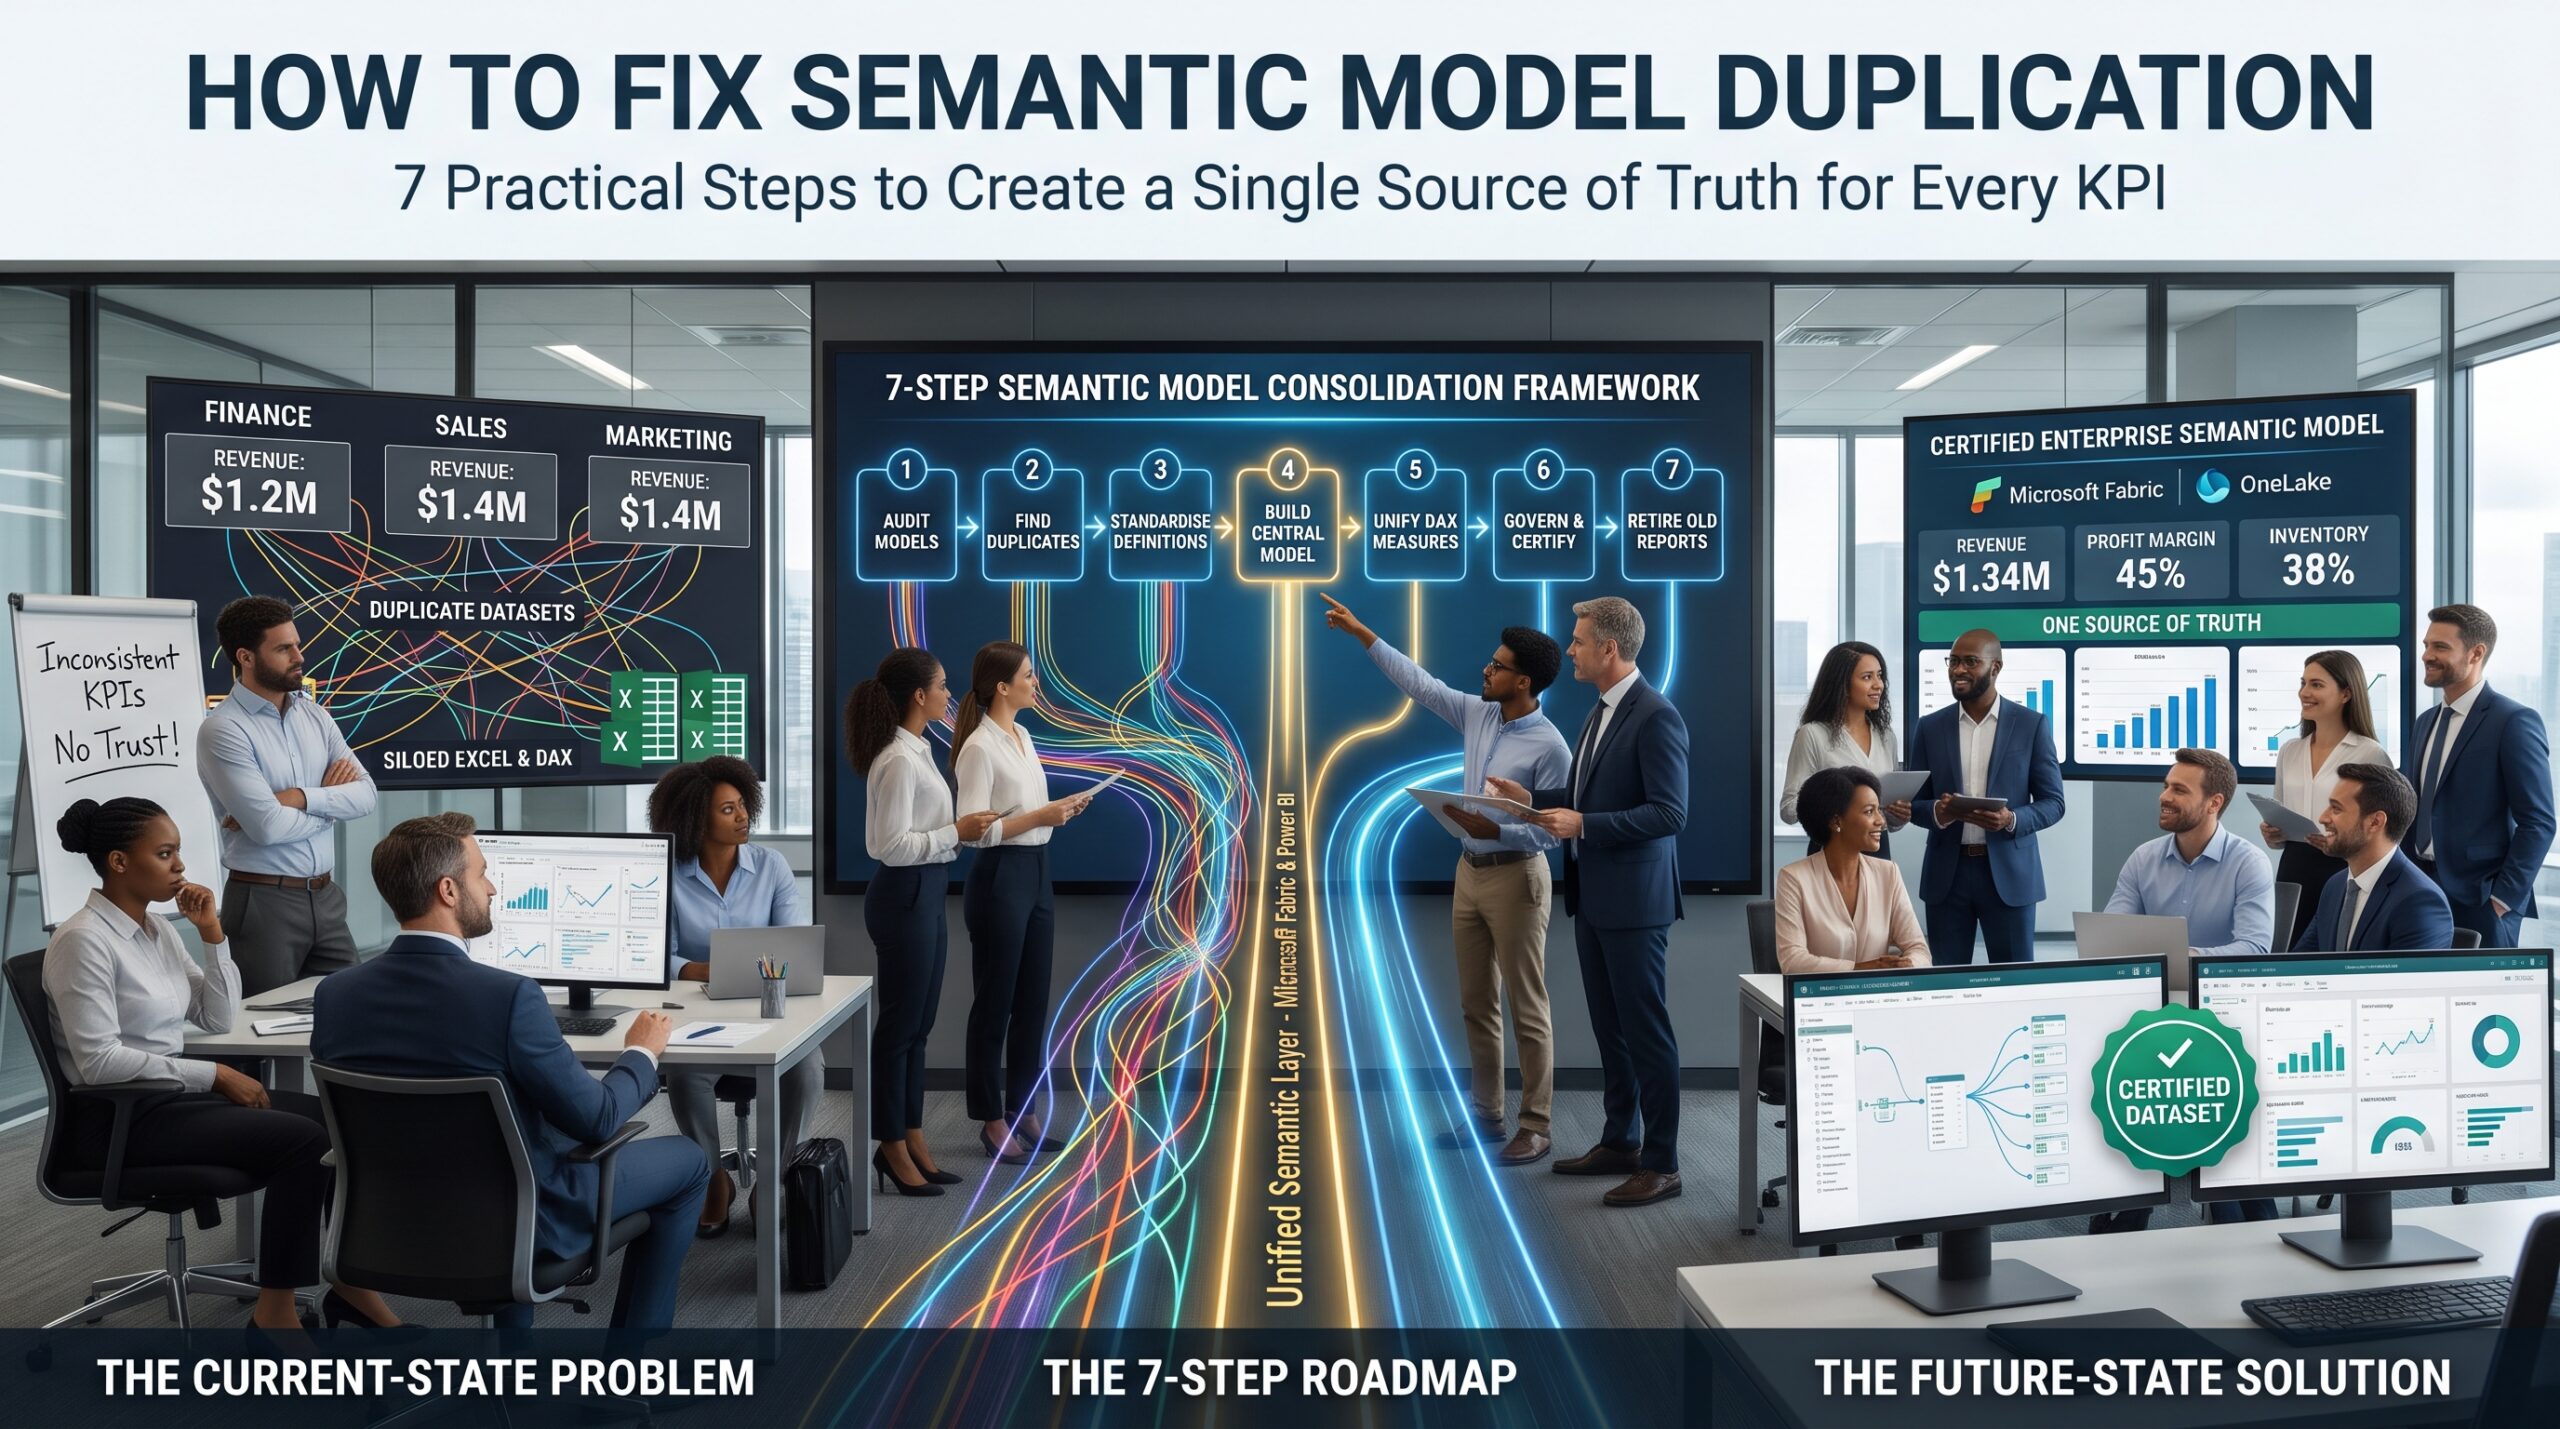
- Take an inventory. List every semantic model, who owns it, which workspace it lives in, and which reports use it. Power BI’s lineage view and admin tools can help you map this.
- Group by business subject. Sales, finance, HR and operations usually need one core model each, not one per report.
- Build one clean model per subject. Use a star schema, with clear fact and dimension tables. Wikipedia’s star schema overview is a good primer.
- Move shared measures into that model. Define each KPI once, name it clearly, and add a description explaining the logic.
- Use thin reports. Connect new reports to the shared model instead of importing data again, and limit report-level measures to genuinely local calculations.
- Endorse and control access. Mark the trusted model as certified, and manage who has permission to build new content on it.
- Retire the duplicates. Redirect reports to the shared model, tell users what’s changing, and delete the old copies once nobody depends on them.
Semantic Model Duplication Prevention Checklist
| Area | What good looks like | Quick check |
| Discoverability | Certified models are easy to find and clearly named | Can a new analyst find the right model in two minutes? |
| Ownership | Every model has a named owner and a backup | Is the owner listed in the model description? |
| Measures | Each KPI is defined once, with documentation | Search for measures with the same name |
| Access | Build permission is granted deliberately | Who can create new reports on this model? |
| Change control | Updates are tested before release | Is there a dev, test and production process? |
| Cleanup | Unused models are retired on a schedule | When was the last review? |
Semantic Model Duplication and Microsoft Fabric
As more organisations adopt Microsoft Fabric, the temptation is to build new models directly on the lakehouse. Done well, that’s a chance to create a single, governed layer. Done badly, it’s one more copy. The principle stays the same: build the model once, define the measures once, and let many reports reuse it. For deeper modelling techniques, the team at SQLBI publishes widely respected material on DAX and data modelling, and the DAX language overview on Wikipedia is a quick reference.
Learn Power BI Modelling and DAX in Australia
Fixing semantic model duplication needs solid modelling and DAX skills, plus the confidence to say “we already have a model for that.” Power BI Course offers practical training for every stage:
- Power BI Beginner Course covers connecting data with Power Query and building your first interactive dashboard.
- Power BI Intermediate Course introduces DAX, drill-through pages, row-level security and governance.
- Power BI Advanced Course tackles complex DAX, time intelligence and enterprise-grade model optimisation.
- PL-300 Microsoft Power BI Data Analyst prepares you for the certification exam.
- DP-600T00 Microsoft Fabric Analytics Engineer suits those building governed analytics in Fabric.
- Introduction to Microsoft Power Platform (PL-900) gives a broad overview of the platform.
Courses are available in person in Melbourne, Sydney and Brisbane, with live online and in-house options elsewhere:
- Power BI course in Melbourne
- Power BI course in Sydney
- Power BI course in Brisbane
- Power BI courses in Perth
- Power BI course in Adelaide
- Power BI course in Canberra
Have questions about prerequisites or delivery? See our Power BI course FAQ.
Semantic Model Duplication FAQs
What is a semantic model in Power BI?
It’s the layer that holds your tables, relationships and measures. Reports and dashboards are built on top of it. It was previously called a dataset.
Why do my Power BI reports show different numbers for the same KPI?
Most often the reports use different models or different measure definitions. Semantic model duplication, report-level measures and mismatched filters are the usual culprits.
How do I find duplicate semantic models?
Start with an inventory of every model and its workspace, then compare table names, measure names and refresh sources. Lineage view and admin tooling can speed this up.
What is a thin report in Power BI?
A thin report connects to an existing shared semantic model rather than carrying its own data. It reuses the model’s measures, so every report gets the same calculation.
Should every report have its own semantic model?
Generally no. A small number of governed, certified models, ideally one per business subject, serves most needs better and keeps numbers consistent.
Final Thoughts: One Model, One Number
Semantic model duplication isn’t a technical failure so much as a coordination one. People build copies because it’s fast and because the trusted model is hard to find. Take an inventory, build a small number of strong models, define each KPI once, use thin reports and retire the clutter. Do that, and “why don’t these numbers match?” stops being a weekly question.
Ready to build these skills? Explore our Power BI courses, read more on the Power BI Course blog, or get in touch to find the right fit.